Agentic AI governance is the discipline of deciding how much authority an AI agent has, for which task, and on what evidence. Treating autonomy as a binary switch creates friction between delivery teams and risk functions. A better approach is to increase autonomy in measured stages, per use case, using evidence the platform itself produces.
Autonomy should be earned, not granted. The platform should generate the evidence required to move from shadow mode to suggestion, approval and ultimately exception-based automation.
The Problem: “Autonomous” Versus “Not Autonomous” Is the Wrong Debate
Enterprises may ask for autonomous AI agents and, at the same time, be unwilling to let them run unattended in regulated, safety-adjacent or high-consequence processes. Both positions can be reasonable. Programmes stall when autonomy is treated as a single go-live decision rather than a capability that can mature in controlled stages.
The result is a standing argument between delivery and risk: the technology team wants to prove value, while the control functions want evidence that the agent is reliable enough to act. Without an agreed progression model, pilots can remain pilots indefinitely. This is one of the recurring patterns behind why technology strategies fail: the plan has no measurable way to move from intent to release.
Make Agentic AI Autonomy a Graduated Release Backed by Evidence
The practical objective is to apply autonomy per use case, not per platform, and to define measurable exit criteria for each stage. This turns the governance discussion from a principle debate into an evidence-based release decision.
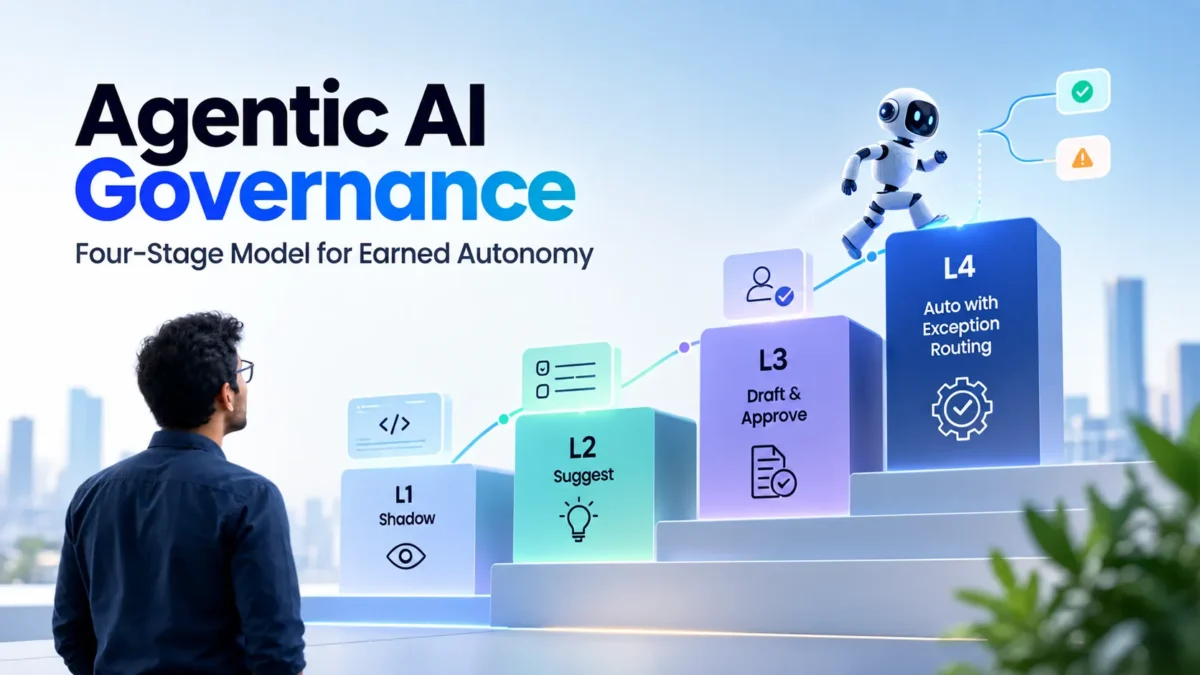
The Four-Stage Earned Autonomy Model
| Gate | Agent behaviour | Typical exit criteria |
|---|---|---|
| L1 – Shadow | Runs alongside the human; output is logged but never surfaced | 2–4 weeks of production-volume traffic captured |
| L2 – Suggest | Output is shown to the user; the human still performs the work | At least 85% suggestion acceptance over 500+ transactions |
| L3 – Draft and approve | Agent produces the artefact; a human approves it | 10% or lower material edit rate; zero critical defects in the review sample |
| L4 – Auto with exception routing | Agent executes and escalates on confidence or policy breach | Stable L3 performance across one full business cycle |
Two Design Decisions That Make the Model Work
1. Build the AI Evaluation Harness From Sprint One
Acceptance rate, edit distance, escalation rate and citation coverage should be logged on every run. Evidence should be produced continuously by the platform rather than reconstructed manually once a month. Teams that design this into the architecture from day one avoid costly retrofits later, which is a core concern of AI, data and intelligent enterprise transformation.
2. Make the Escalation Threshold a Business Parameter
The confidence threshold that triggers escalation should be configurable and owned by the process owner, not buried as a constant in a prompt or orchestration script. When the business can see and adjust the threshold, human in the loop AI becomes a governed control rather than an engineering afterthought.
What to Measure at Every Stage of AI Agent Governance
| Metric | What it tells leadership |
|---|---|
| Suggestion acceptance | Whether users find the agent output useful enough to adopt |
| Material edit rate | How much human rework is required before the output can be approved |
| Escalation rate | How often the agent identifies that it should not proceed automatically |
| Citation coverage | Whether generated outputs remain traceable to approved evidence where grounding is required |
The point is not to chase a single “AI accuracy” score. It is to collect the operating evidence that matters for the specific business process and release stage. This mirrors the principle in measuring whether technology investments create business value: metrics must connect to outcomes leadership actually cares about.
Autonomy Can Create Value Before Full Automation
A staged model also changes the commercial conversation. In practitioner delivery experience, meaningful benefit can be demonstrated at L2 and L3, often through reduced search, drafting or review effort, before anyone signs off on fully unattended execution.
The source delivery experience documented for this framework observed effort reduction in the 30–45% range at these intermediate stages. That allows the business case to develop without making funding dependent on an all-or-nothing promise of full autonomy. You can see how this plays out in practice in our AI and data engineering case study.
A Practical Agentic AI Governance Sequence
- Start in shadow mode. Capture production-volume behaviour without changing the user process.
- Expose suggestions only after evidence exists. Use acceptance data to understand whether the agent is adding value to the workflow.
- Move to draft-and-approve when quality stabilises. Track material edit rate and critical defects instead of relying on subjective confidence.
- Allow execution only after a full business cycle is stable. Keep exception routing active so low-confidence or policy-sensitive cases return to a named human.
- Reassess by use case. One process may be ready for L4 while another on the same platform remains at L2. Autonomy is a workload decision, not a platform-wide setting.
Where agents touch personal data, regulated records or safety-adjacent workflows, this sequence should sit alongside your wider cybersecurity, privacy and compliance controls so that each autonomy release is also a risk-approved release.
Practitioner view: Autonomy is not a feature toggle. It is a release decision supported by measurable evidence, applied use case by use case.
The Executive Takeaway
Agentic AI governance becomes more practical when autonomy is observable, measurable and reversible. A staged model gives technology, operations and risk teams a common language: what the agent is allowed to do now, what evidence is being collected, and what must be true before the next level of autonomy is released.
Build the evaluation harness into the product from the beginning. Make escalation thresholds visible to the business. Earn autonomy through evidence rather than assumption. If your organisation lacks in-house leadership to set this direction, a fractional CTO can own the governance model and the roadmap that supports it. See also our guide to choosing between a fractional and interim CTO.
Frequently Asked Questions
What does “earned autonomy” mean in agentic AI?
It means increasing the agent’s authority in stages only after measurable performance criteria are met. A use case can move from shadow mode to suggestion, approval and automated execution without treating autonomy as an all-or-nothing launch decision.
Should every AI agent reach full autonomy?
No. The framework is applied per use case. Some processes may create sufficient value at suggestion or draft-and-approve stages, particularly where regulation, safety or professional judgement requires human accountability.
What should an agentic AI evaluation harness capture?
The practitioner framework emphasises acceptance rate, material edit rate, escalation rate and citation coverage, captured on every run rather than through occasional manual sampling.
Need a Practical Agentic AI Governance Model?
SYNAPLAB helps leadership teams define staged autonomy, measurable evaluation criteria and business-controlled escalation for enterprise AI workflows. Explore our services, learn about our team, browse more insights, or contact us at connect@synaplab.io.